Projects and Resources
Software and Projects7 items
2026
Guidelines for Spoken Language UD Treebanks. Draft guidelines for annotating spoken-language treebanks in Universal Dependencies, produced by the UniDive WG1 T1.5 group. I co-coordinate the project.
2026
2026
Corpus Annotation Tools. Tools for corpus annotation developed within a separate project.
2025
2023
Catenae. Code accompanying my PhD work on constructionist approaches to language models.
Datasets3 items
2026
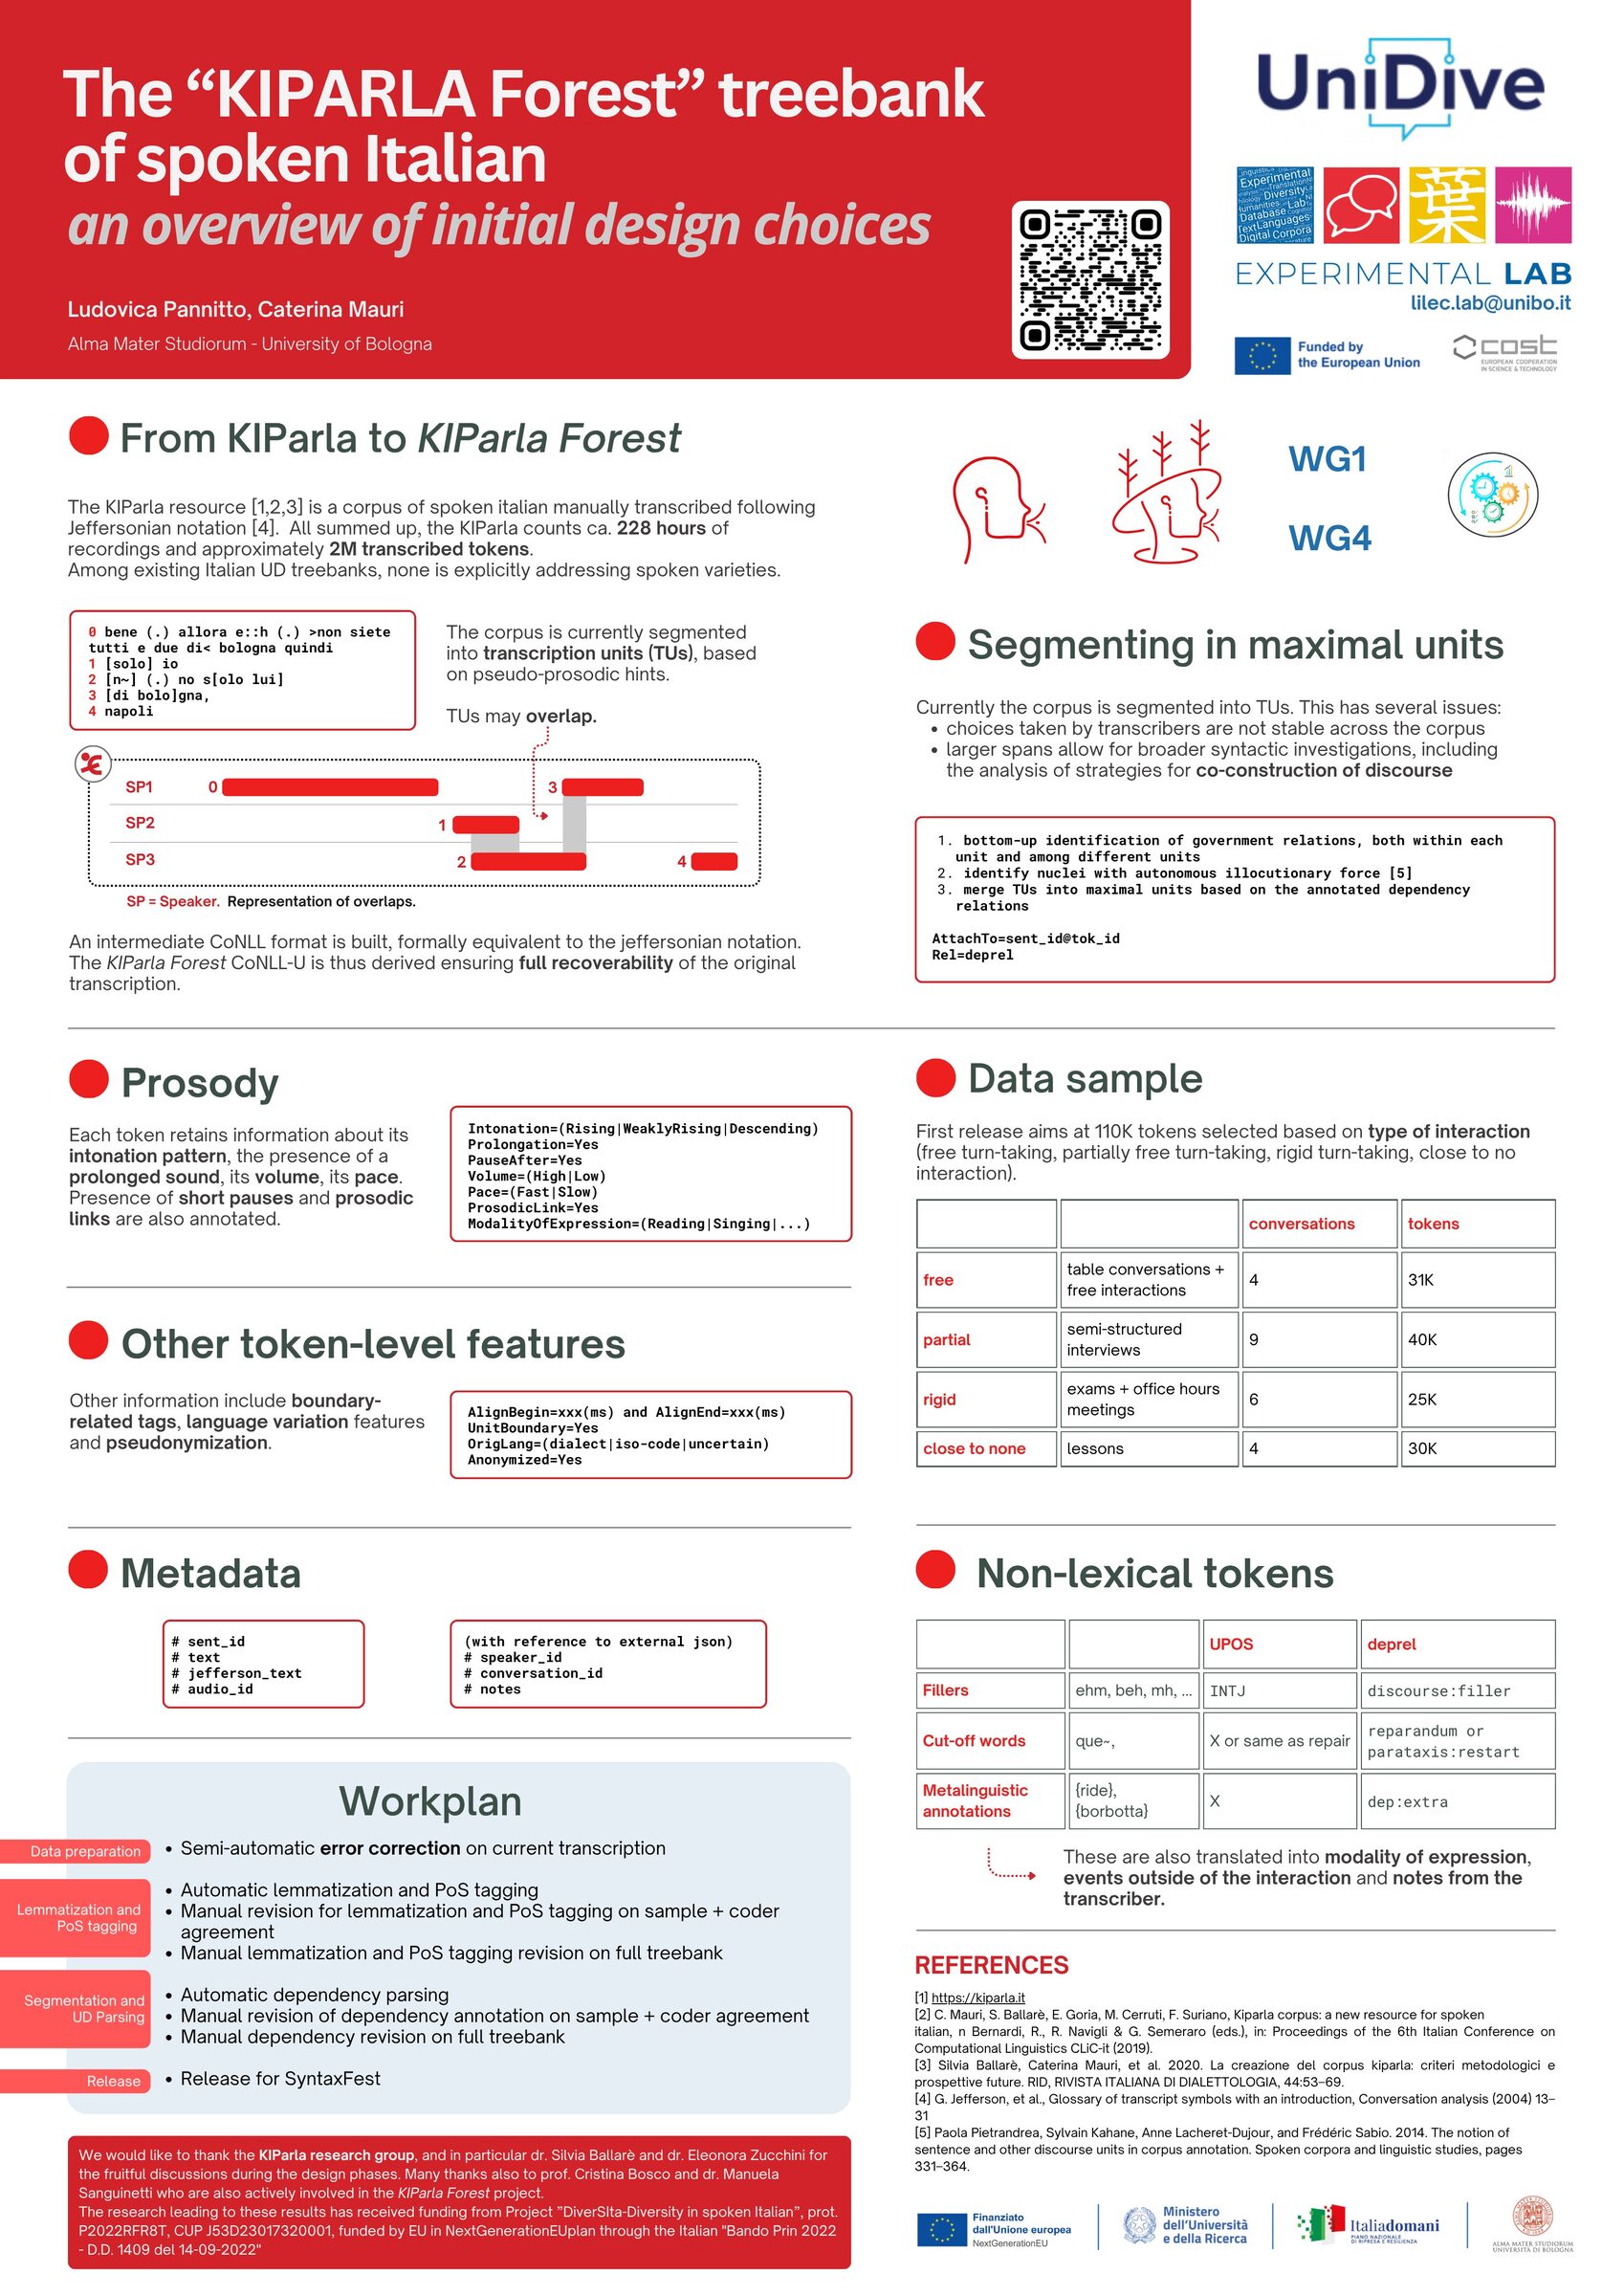
2020
Outreach and Dissemination3 items
2021
Teaching NLP Workshop Materials. Supplementary material for the Teaching NLP workshop paper on interactive outreach for Italian students.
2021
2020
Bright-Night Outreach Materials. Materials for the Bright-Night presentation on computational linguistics outreach.
Inspired by the modular cabinets of the Olivetti ELEA 9003, designed by Ettore Sottsass (1959).
Back to top